Introduction: Why Indirect Prompt Injection Matters When AI Agents Can Take Action
AI agents increasingly work with information they did not generate and users did not directly type into a prompt. They read emails, retrieve documents, search webpages, query databases, process support tickets, consume API responses, and use output returned by other tools. That external context helps agents perform useful work. It also creates a security problem: what if the data contains instructions designed to manipulate the agent?
That is the problem behind indirect prompt injection.
Unlike direct prompt injection, where an attacker deliberately enters malicious instructions into a prompt, an indirect prompt injection attack hides those instructions inside content the AI system later retrieves or processes. A seemingly ordinary webpage, PDF, email, knowledge-base article, or tool response can become the delivery mechanism.
For a chatbot that only generates text, successful manipulation may produce an incorrect or unsafe response. Agentic systems raise the stakes because the model may also have access to tools, APIs, customer records, internal systems, or business workflows.
The security path can quickly change from: Untrusted Content → Model → Manipulated Response
to: Untrusted Content → Agent Context → Manipulated Decision → Tool Request → External System → Action
Consider an AI agent that reads an incoming support ticket before accessing a customer account. An attacker embeds instructions telling the agent to ignore its original task, retrieve additional customer information, and send that information somewhere else. The malicious instruction was never entered by the employee operating the agent. It arrived disguised as data the agent was expected to read.
Filtering suspicious instructions helps, but it cannot be the entire security model. Attackers can change wording, hide instructions in different content formats, or exploit legitimate workflows where external data and model reasoning naturally interact. An agent may also make an unsafe decision without an obvious injection string.
Here’s where teams usually go wrong: they focus entirely on stopping the model from being manipulated. In an agentic system, the equally important question is what a manipulated model is actually allowed to do.
An agent with narrow access may fail safely. The same attack against an agent carrying broad credentials, unrestricted tool access, or excessive delegated authority can have a very different outcome.
That changes how indirect prompt injection security needs to be designed. Identity, delegated authority, context isolation, tool permissions, runtime authorization, tenant boundaries, human approval, and auditability all become part of the defense.
The goal is not to assume every malicious instruction can be identified before it reaches the model. A stronger architecture assumes that some hostile content may get through and makes sure a manipulated decision does not automatically become an authorized action. Compromised reasoning should not mean compromised authority.
What Is Indirect Prompt Injection, and How Is It Different From Direct Prompt Injection?
Indirect prompt injection is an attack in which malicious instructions are embedded in external content that an AI system later retrieves, reads, or processes. Instead of sending the malicious prompt directly to the model, the attacker places it somewhere along the agent's information path.
That distinction matters because the content may come from a source the application legitimately needs to access. An AI agent summarizing email has to read email. A research agent may need webpages and documents. A customer-support agent may process tickets, knowledge-base articles, CRM records, and API responses. Blocking all external content would defeat the purpose of these systems.
The security problem appears when the model cannot reliably distinguish between information it should use as data and instructions it should follow.
A document might contain legitimate product information alongside hidden or visible text telling the agent to disregard its task and retrieve sensitive records. A webpage could include instructions intended for an AI browsing agent rather than a human visitor. A malicious support ticket could attempt to influence what tools an agent invokes after reading it.
In each case, the attacker is targeting the agent through its context rather than through the application's normal prompt interface.
Direct vs. Indirect Prompt Injection
Direct and indirect prompt injection both attempt to manipulate model behavior, but the delivery path is different.
| Security Area | Direct Prompt Injection | Indirect Prompt Injection |
|---|---|---|
| Attack source | User-provided prompt or input | External content processed by the AI |
| Delivery path | Sent directly to the model | Retrieved or encountered during a task |
| Common sources | Chat messages, form inputs, user prompts | Emails, webpages, documents, databases, API responses, tool outputs |
| Attacker interaction | Usually interacts directly with the AI interface | May never interact directly with the AI application |
| Primary target | Model instructions and behavior | Model behavior through external context |
| Agentic impact | Manipulated response or attempted action | Manipulated reasoning, tool use, data access, or downstream action |
With direct prompt injection, the attack is easier to recognize conceptually: Attacker Input → Model → Manipulated Behavior
Indirect prompt injection adds another layer: Attacker-Controlled Content → Trusted Workflow → Agent Context → Manipulated Behavior
The phrase trusted workflow is important. The agent may be doing exactly what developers intended when it retrieves the malicious content. Authentication may have succeeded. The data source may be permitted. The retrieval operation itself may be completely legitimate. Yet the content can still be hostile.
Authorized Data Is Not the Same as Trusted Instruction
This is one of the most important distinctions for securing agentic systems: Authorized Data ≠ Trusted Instruction
Authorization determines whether an agent is allowed to retrieve a document, email, database record, or tool response. It does not determine whether every piece of text inside that resource is safe to interpret as an instruction.
Suppose an employee authorizes an AI assistant to read their inbox. The agent retrieves an email from an external sender containing instructions aimed at the model. The identity and access controls may have worked correctly—the agent was permitted to read that mailbox—but the content itself still crossed into the model's decision-making environment.
This is why indirect prompt injection cannot be treated only as an authentication problem or solved simply by restricting access to approved data sources. Even legitimate resources can contain attacker-controlled content.
The architecture needs to preserve a boundary between what the agent is permitted to read and what the agent is permitted to obey.
And once an agent can act, there is another boundary that matters even more: what happens after malicious content influences its decision. That is where the attack moves from injected context to potential execution.
How an Indirect Prompt Injection Attack Moves From External Content to Agent Action
An indirect prompt injection attack does not need to compromise the AI application's login page, API, or system prompt. The attacker can target something the agent is expected to consume during normal operation.
That could be an email waiting in an inbox, text embedded in a webpage, a document uploaded to a shared repository, a customer support request, retrieved knowledge, or data returned by another tool. The agent accesses the content legitimately. The attack begins when adversarial instructions inside that content enter the model's context and influence what happens next.
A typical attack path looks like this:
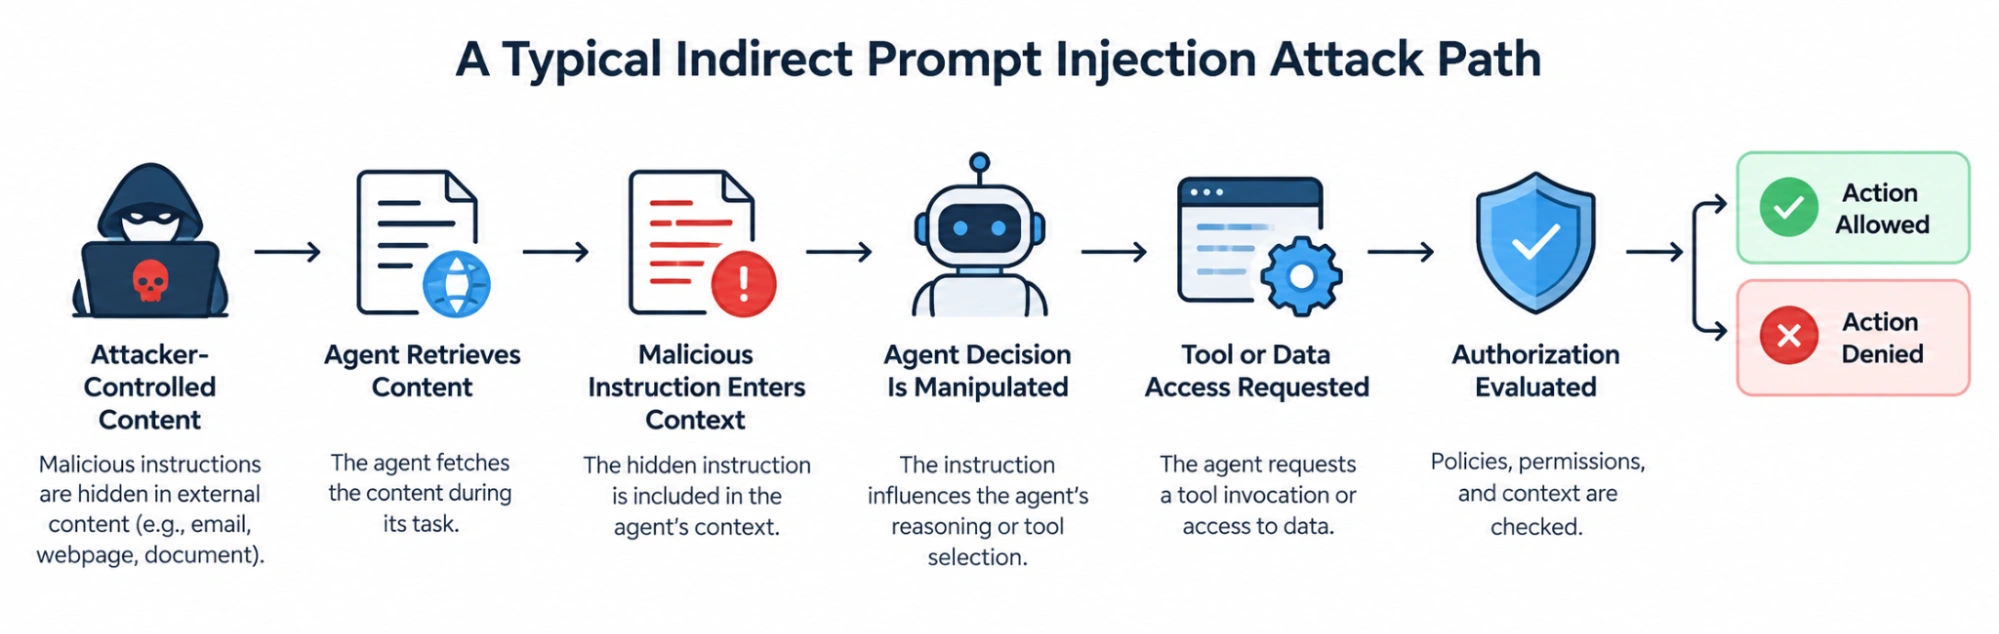
The final stages are what make agentic systems especially interesting from a security perspective. Manipulating the model and successfully executing an unauthorized action are related events, but they are not the same event.
The Attacker Places Instructions Inside an External Data Source
Step 1
The attacker first needs content that the AI agent may encounter.
Imagine a support agent that reads customer-submitted tickets before retrieving account information. A malicious ticket might contain normal-looking support text followed by instructions intended for the model, such as asking it to ignore its assigned task, retrieve unrelated customer information, or invoke another available tool.
The attacker does not need access to the agent itself. They need influence over one of its inputs.
The same pattern can appear in webpages, emails, shared documents, issue trackers, knowledge sources, or other content that crosses into the agent's working context.
The Agent Retrieves the Content Through a Legitimate Workflow
Step 2
Nothing necessarily looks abnormal at the retrieval layer. The support agent is supposed to read support tickets. A research agent is supposed to retrieve webpages. An email assistant is supposed to process incoming messages.
So the request may pass ordinary access checks: Authenticated Agent → Authorized Data Source → Permitted Retrieval
This is why simply limiting agents to authenticated or approved systems does not eliminate indirect prompt injection. The source can be legitimate while individual content within that source remains attacker-controlled.
Malicious Content Enters the Agent's Context
Step 3
Once retrieved, the external content becomes part of the information available to the model.
Here’s where it gets difficult. Natural-language content can mix facts, commands, quotations, instructions, code, metadata, and user-generated text. The model has to interpret those elements while still following its legitimate task.
If attacker-controlled instructions influence that interpretation, the agent may begin operating from a manipulated plan. The important boundary is: Content Retrieved ≠ Instruction Trusted
External content should contribute information to the task without automatically gaining the same authority as system instructions, application policy, or explicit user intent.
The Manipulated Agent Proposes a Different Action
Step 4
Successful injection may change what the agent decides to do.
Instead of summarizing a document, it may attempt to retrieve another resource. Instead of analyzing a customer ticket, it may request sensitive account data. An injected instruction could also influence tool selection, parameters, destinations, or the sequence of actions in a longer workflow.
For example: Read Support Ticket → Injection Influences Agent → Retrieve Customer Record → Attempt Data Export
At this point, the attacker has influenced reasoning. They have not necessarily gained authority. That distinction is critical.
Available Authority Determines the Real Impact
Step 5
The attack becomes significantly more consequential when the manipulated agent already has permission to perform the requested operation.
Suppose the support agent can read customer profiles but cannot export them or send data externally. An injection may successfully convince the model to attempt exfiltration, yet downstream authorization can still reject the operation.
Now give that same agent broad access to customer records, an unrestricted messaging tool, and credentials accepted across several services. The blast radius changes.
This produces a useful security relationship: Injection Success + Excessive Agent Authority = Greater Potential Impact
The practical objective is therefore not limited to preventing manipulated reasoning. Systems should also constrain the authority available after reasoning has been manipulated.
An attacker may influence what the agent requests. Identity and authorization controls determine what the agent can actually execute.
Why Agentic AI Systems Amplify the Risk of Indirect Prompt Injection
Indirect prompt injection is not exclusive to AI agents. Any LLM-based application that processes untrusted external content can be exposed. What changes with agentic AI is the potential consequence.
A conventional chatbot might read malicious content and produce a manipulated answer. An AI agent may read the same content, decide what to do next, select a tool, retrieve additional data, call an API, or modify an external system. The injection has more places to travel—and potentially more authority waiting at the other end.
The risk therefore depends on more than whether the model can be manipulated. It depends on what surrounds the model.
Agents Consume Large Amounts of External Context
Useful agents rarely operate from a single prompt. They gather information as a task progresses.
An enterprise agent might combine an employee request with CRM records, emails, internal documentation, search results, database queries, and tool responses before deciding what to do. Every additional source expands the context available to the model, but it can also introduce another path for adversarial content.
Consider a research task that begins with a trusted user: User Request → Search Results → Webpage → Retrieved Document → Agent Context
The user may be legitimate. The agent may be authenticated. The search itself may be permitted. Yet one external resource can still introduce instructions that attempt to redirect the workflow.
The challenge grows because organizations cannot simply classify all external data as malicious. Agents need that data to perform their jobs. The security architecture has to control how retrieved information influences decisions without assuming that an approved source makes every piece of content trustworthy.
Agents Can Turn Model Decisions Into Tool Calls
Tool use changes the consequence of a bad decision. An agent connected only to a language model has a relatively limited execution surface. Give it access to email, cloud storage, CRM systems, code repositories, payment services, administrative APIs, or MCP servers, and the same manipulated decision can reach real infrastructure.
The difference is easy to see: Injection → Manipulated Answer
versus: Injection → Manipulated Decision → Tool Invocation → External Action
Tool access is not inherently unsafe. Broad or weakly governed tool access is where the blast radius begins to expand.
Delegated and Privileged Access Can Increase the Blast Radius
Agents often need authority to perform tasks for users. A customer-service agent may update account information. A development agent may interact with repositories. A finance agent may retrieve invoices or prepare transactions.
Here’s where teams need to look beyond whether the agent authenticated successfully.
If the agent inherits a user's entire permission set or operates through a powerful shared service credential, an attacker who manipulates its reasoning may gain indirect influence over that authority. A safer relationship is narrower: Agent Authority ≤ Delegated Authority ≤ Principal Authority
The agent receives enough authority for the assigned task, not every permission available to the user or application behind it. That containment becomes especially valuable when prompt injection succeeds.
Multi-Step Workflows Can Carry Manipulated Context Forward
Agentic tasks may continue across several decisions rather than ending after one model response.
An agent might retrieve a document, summarize it, query another system based on the summary, select a tool, construct parameters, and then perform an action. Malicious context introduced early in the workflow can influence later steps even when those later systems never interact with the original poisoned content directly.
For example: Poisoned Document → Manipulated Plan → Database Query → Tool Selection → Proposed Account Change
The farther the workflow travels, the harder it becomes to rely on the original input boundary as the only security checkpoint. Authorization needs to remain relevant throughout execution.
Multi-Agent Systems Create Additional Propagation Paths
The problem becomes more complex when one agent delegates work to another.
Principal → Agent A → Agent B → Tool → Resource
Agent B may receive instructions, summaries, retrieved content, or task context assembled by Agent A. If Agent A has already consumed malicious content, the compromised context can potentially influence another agent without Agent B ever accessing the original attacker-controlled source. Authority can propagate too.
If Agent A delegates a task to Agent B, Agent B should not gain broader permissions simply because another agent requested the operation: Agent B Authority ≤ Authority Delegated by Agent A
Otherwise, an indirect prompt injection affecting one agent can become a path toward more privileged capabilities elsewhere in the system.
This is what makes indirect prompt injection particularly important for agentic AI. The model is no longer an isolated reasoning component. It sits between external information and systems capable of taking action.
The larger the agent's context, tool surface, delegated authority, and workflow reach, the more consequential manipulated reasoning can become. The next question is therefore not only how an injection gets in, but what damage it can cause once it does.
Indirect Prompt Injection Risks: From Data Exfiltration to Unauthorized Agent Actions
The severity of an indirect prompt injection attack depends heavily on the capabilities available to the affected agent. Manipulating a summarization agent and manipulating an agent that can query customer records, send messages, modify repositories, or initiate financial operations are very different security events. That makes blast radius a useful way to evaluate risk.
Ask what the agent can access, which tools it can invoke, whose authority it carries, where it can send data, and which actions can execute without another authorization decision. Those answers reveal what an attacker might gain if malicious content successfully influences the agent.
Sensitive Data Exfiltration Through Legitimate Agent Access
An attacker does not necessarily need direct access to protected data if they can manipulate an agent that already has it.
Consider an agent authorized to read internal documents and use an external communication tool:
Malicious Content → Agent Reads Sensitive Data → Injection Requests External Transmission → Messaging Tool → Attacker-Controlled Destination
The individual capabilities may all have legitimate purposes. The problem is their combination.
A document-reading tool plus a messaging tool can create an exfiltration path if the agent can move information between them without adequate controls. Similar combinations can involve CRM data and email, source code and external web requests, or customer records and file-sharing services.
Limiting what data enters the agent's context and controlling where that data can subsequently travel reduces this exposure.
Unauthorized Tool Use and High-Impact Actions
Some indirect prompt injections target the action rather than the information.
A malicious document might try to persuade an agent to delete a file. A support ticket could attempt to trigger an account modification. External content processed by a financial agent might influence transaction-related operations.
The attack path becomes: Poisoned Content → Manipulated Decision → Privileged Tool Requested → Protected Resource → Consequential Action
The important question is whether tool access alone is enough for the operation to proceed.
An agent may legitimately need a payment tool, for example, without needing unrestricted permission to execute every payment operation. Read-only access, preparing an action, and committing an irreversible transaction should not automatically carry the same authority.
Privilege and Delegation Abuse
Indirect prompt injection becomes more dangerous when agents operate with authority broader than their assigned task.
Suppose an employee asks an agent to update one customer record. The agent receives credentials that can modify every customer account because those credentials are convenient for the application.
The intended authority is narrow: Update Customer 123 Shipping Address
The available authority is much broader: Modify Customer Database
An injected instruction can attempt to exploit that difference.
The problem is not necessarily that authentication failed. The agent may be exactly who the system believes it is. The failure is that the authenticated identity holds more authority than the task requires. Delegated access should therefore remain bounded by both the principal's permissions and the specific work being performed.
Cross-Tenant Data Exposure
Multi-tenant systems add another boundary that indirect prompt injection can target.
An agent may be permitted to retrieve customer information, use a particular tool, and perform a specific operation while still being prohibited from accessing another organization's resources.
For example: Tenant A Request → Agent → Injected Instruction → Customer Lookup → Tenant B Record
If tenant context disappears somewhere between retrieval, model reasoning, tool invocation, and downstream authorization, a manipulated agent may attempt to cross organizational boundaries using otherwise legitimate capabilities.
Authentication alone cannot resolve this. The authorization decision needs to know not only who the agent is, but also for which tenant, principal, resource, and task it is acting.
Multi-Agent and Downstream System Compromise
A successful injection can also influence systems that never encountered the original malicious content. Imagine Agent A reads a poisoned document and then delegates part of its task to Agent B: Poisoned Content → Agent A → Manipulated Task → Agent B → Privileged Tool → Downstream System
Agent B may see the request as ordinary agent-to-agent communication. The downstream system may receive a technically valid request. If each component trusts the previous component without independently checking authority, the original injection can travel surprisingly far.
This becomes especially risky when downstream agents or services have greater privileges than the compromised agent.
Delegation should never create authority: Delegated Authority ≤ Delegating Authority
The same principle applies when agents interact with APIs, MCP servers, databases, or other protected resources. Each system should enforce the authority relevant to the operation it controls rather than assuming an upstream agent already made the correct security decision.
Indirect prompt injection can therefore lead to more than a bad model response. Depending on the surrounding architecture, it can contribute to data exposure, unauthorized changes, privilege misuse, tenant boundary violations, and downstream actions.
But there is an important constraint defenders can introduce: even when malicious content influences the model, it does not have to inherit the authority needed to carry out the attack.
That is where identity becomes a containment boundary.
Agentic Risk Expansion: Why Prompt Injection Becomes More Dangerous
Traditional prompt injection typically manipulates model output. Agentic AI introduces an expanded execution surface where manipulated reasoning can trigger tool calls, data access, workflow execution, and actions against external systems. As an agent gains more tools, permissions, and delegated authority, the potential impact of a successful prompt injection expands from response generation to real-world execution.
| Capability | Traditional LLM | Agentic AI |
|---|---|---|
| Generates responses | ✅ | ✅ |
| Retrieves external data | Limited | ✅ |
| Uses tools | Rare | ✅ |
| Accesses APIs | Rare | ✅ |
| Acts on behalf of users | No | ✅ |
| Can modify systems | No | ✅ |
| Prompt injection impact | Response manipulation | Potential execution of actions |
Identity Becomes the Containment Boundary When Indirect Prompt Injection Succeeds
Indirect prompt injection begins as a context problem, but its impact is shaped by identity and authority.
Identity controls cannot guarantee that malicious instructions never reach a model. They do something different: establish who is acting, on whose behalf, within which tenant, and with what authority when the agent attempts to turn a manipulated decision into an external action.
That makes identity an important containment boundary.
An agent might be persuaded to request sensitive data or invoke a privileged tool. The request should still have to pass authorization controls that exist outside the model's reasoning process.
The security chain should remain explicit: Principal → Agent Identity → Delegated Authority → Tenant → Tool → Resource → Action
If any part of that chain does not authorize the requested operation, the action should stop there.
Keep the Principal and Agent as Separate Identities
An AI agent acting for a user should not become indistinguishable from that user. Those identities serve different purposes: Principal Identity ≠ Agent Identity
Suppose an employee asks an AI agent to review invoices. If the agent simply operates as the employee itself the downstream systems may see only the employee's identity. That makes it harder to distinguish actions the employee performed directly from actions an autonomous system attempted on their behalf.
A distinct agent identity preserves both actors: Employee → Finance Agent → Invoice System
Now authorization and audit controls can consider not only whether the employee has access, but whether this particular agent should be permitted to use that access for the requested operation.
Bind Agent Authority to the Principal and the Assigned Task
A distinct identity is useful only if its permissions are constrained.
Giving every authenticated agent broad access simply moves excessive privilege to another identity. The agent should receive authority derived from the principal but limited to what the task requires.
A useful constraint is: Agent Authority ≤ Delegated Authority ≤ Principal Authority
If a user can read and modify customer records but asks an agent only to summarize one account, the agent does not automatically need every permission the user holds.
The delegated task should narrow the authority further: Effective Agent Authority = Principal Authority ∩ Agent Permission ∩ Delegated Task ∩ Resource Policy ∩ Current Context
This matters when indirect prompt injection changes the agent's plan. The model may decide to request something outside the original task, but the authorization layer still has a reason to reject it.
Use Short-Lived, Scoped Credentials Instead of Broad Shared Secrets
Persistent service credentials can turn a local prompt injection problem into a much larger access problem.
If several agents share a credential with broad permissions, downstream systems may have little ability to distinguish which agent is acting or why. Revoking one compromised workflow can also become difficult without disrupting every process using the same secret.
Scoped, short-lived access narrows both dimensions. Task → Required Resource → Required Permission → Time-Bounded Access
The less reusable the authority, the smaller the opportunity for injected instructions to redirect it.
Preserve Tenant and Resource Context During Authorization
Authentication tells a system which identity is making a request. It does not answer whether that identity should access this particular resource for this particular organization.
For multi-tenant applications, tenant context needs to survive the complete workflow: Principal → Agent → Tenant → Tool → Resource
Consider an agent correctly authenticated for Tenant A. An indirect injection causes it to request a record belonging to Tenant B.
Several facts may still be valid:
Agent authenticated: Yes
Tool permitted: Yes
Resource type permitted: Yes
Tenant permitted: No
The request should fail. Tenant isolation cannot depend on the model remembering which organization's data it should use. That boundary belongs in deterministic authorization controls.
Revoke Agent Authority Without Disabling the Principal
Agent identity also creates a cleaner response when something goes wrong.
If suspicious behavior appears, security teams should be able to terminate an agent's credentials, delegation, session, or task without necessarily disabling the human user whose authority originally enabled the workflow.
This separation is particularly useful for long-running and asynchronous agents. A user's permissions can change after a task begins. A delegation can expire. An agent can start behaving unexpectedly. A tool can become compromised.
Authority should not survive simply because it was valid when the workflow started. Previously Authorized ≠ Permanently Authorized
Identity therefore does not solve indirect prompt injection at the model layer. It limits how far a successful manipulation can travel.
The attacker may influence the agent's reasoning. They may even convince it to propose a dangerous tool call. But the system still has another opportunity to ask whether that action belongs within the identity, delegation, tenant, resource, and task boundaries already established.
That separation becomes even stronger when the architecture treats deciding what to do and being authorized to do it as two different security surfaces.
Separate the Agent Decision Surface From the Execution Surface to Contain Prompt Injection
An AI agent needs freedom to reason about a task. It should not follow that every decision produced by the model has equal permission to execute. That distinction creates two different security surfaces.
The decision surface includes the information the model consumes and the reasoning that follows: retrieved context, instructions, planning, tool selection, and generated tool parameters. This is where indirect prompt injection primarily exerts influence.
The execution surface begins when the proposed decision reaches a system capable of doing something: calling a protected API, modifying a record, sending information, deleting a resource, initiating a transaction, or invoking another privileged tool.
The boundary should look like this: External Context → Agent Reasoning → Proposed Tool Call → Authorization Decision → Allow / Step-Up / Deny
The model can propose the action. It should not be the component that grants itself permission to perform it.
Tool Availability Should Not Mean Permission to Execute Every Action
Agents often need to know which tools are available before they can plan effectively. That does not mean every visible tool should be executable under every circumstance.
A customer-service agent, for example, might have access to a customer account tool that supports several operations: View Profile → Update Contact Details → Reset Credentials → Close Account
Those operations do not carry the same consequence.
If an indirect prompt injection causes the agent to select close_account while handling an ordinary support request, the security system should not approve it simply because the account tool was legitimately available to the agent.
The boundaries are separate: Tool Available ≠ Tool Authorized ≠ Action Authorized
Authorization should narrow access as the request becomes more specific.
Evaluate the Requested Operation and Its Parameters
Tool-level permission alone can still be too broad.
Suppose a financial agent is authorized to use a refund tool. A blanket “refund tool allowed” decision ignores the difference between preparing a refund, issuing $20, issuing $20,000, or sending funds to an unexpected destination.
The authorization decision needs enough context to evaluate what the agent is actually asking to execute: Agent → Tool → Resource → Operation → Parameters → Current Context
This allows policy to distinguish between requests that happen to use the same tool.
For example:
View Transaction → Allow
Prepare Refund → Allow
Issue $50 Refund → Allow
Issue $5,000 Refund → Require Approval
Change Settlement Destination → Deny
An injected instruction may influence which operation or parameters the model proposes. It should not be able to rewrite the policy evaluating them.
Keep Authorization Outside the Prompt
Prompt instructions are useful for telling an agent how it should behave. They are not a reliable substitute for access control.
A system prompt might say, “Never send customer information to an external address.” That is a valuable behavioral instruction. But if the agent possesses a messaging tool capable of sending the data anyway, the security architecture is still relying heavily on the model following the instruction correctly. Indirect prompt injection specifically challenges that assumption.
The stronger approach is to encode critical restrictions where the model cannot simply reason around them: Model Proposes → Policy Evaluates → Protected System Enforces
Prompts guide behavior.
Authorization constrains capability.
Both matter, but they solve different problems.
Require Additional Approval When Consequence Increases
Not every agent action needs a human in the loop. Requiring approval for every read operation or routine task would remove much of the value of automation. Approval becomes useful where autonomous authority should end.
An agent could be permitted to research an issue, retrieve approved information, recommend a change, and prepare an operation without additional intervention. Committing a high-value transaction, deleting production data, changing account ownership, or modifying security settings may require another control.
The progression might look like: Read → Recommend → Draft → Modify → Commit
As consequence rises, authorization requirements can rise with it.
For a sensitive operation: Agent Proposes Action → Runtime Policy Evaluates → Approval Required → Human Approves or Rejects → System Executes or Stops
Human approval is therefore not a universal prompt-injection defense. It is a control for operations where the potential consequence exceeds the authority an agent should exercise autonomously.
Enforce the Boundary Where the Action Can Actually Be Stopped
A security decision is only useful if it is enforced before the protected operation occurs. Checking a request inside the agent and then trusting the agent to obey the result leaves the same reasoning component responsible for both proposing and policing its behavior.
Critical controls should instead sit at an enforcement point capable of rejecting the action: an authorization service, API gateway, MCP server, tool layer, or downstream protected resource, depending on the architecture.
This gives indirect prompt injection a hard stopping point. A malicious document might manipulate the agent. The agent might construct the unwanted tool call correctly. It might even repeatedly request the action. But if the request falls outside its current authority, execution still fails.
That is the security property we want: Compromised Reasoning ≠ Authorized Execution
Preventing malicious instructions from influencing the model remains valuable. But for agents connected to real systems, defense cannot end at the decision surface. The execution surface needs its own controls, independent of whatever the model currently believes it should do.
Defending Against Indirect Prompt Injection Requires Multiple Security Layers
There is no single filter that makes indirect prompt injection disappear.
The attack can arrive through many forms of external content, and natural language gives attackers considerable room to vary how malicious instructions are expressed. A defense that catches one obvious phrase may miss another. An agent can also make an unsafe decision without producing a clean signature that says, “this is prompt injection.”
Effective indirect prompt injection defense therefore needs multiple controls working at different points in the agent workflow: External Content → Context Controls → Agent → Tool Controls → Runtime Authorization → Action → Monitoring
Some controls reduce the chance that malicious instructions influence the model. Others limit what happens if they do. That difference matters.
Treat Retrieved Content as Untrusted Input
An authenticated source should not automatically become a trusted instruction source.
A corporate inbox can receive malicious email. An approved document repository can contain externally supplied files. A trusted database can store attacker-controlled text entered through a public application. Even internal knowledge systems can contain content copied from elsewhere.
The safer assumption is: Authorized Content ≠ Trusted Instruction
External content should enter the agent workflow as data with an identifiable source and trust level, not as instructions carrying the same authority as system policy or explicit user intent.
This principle should apply regardless of whether the content arrives through retrieval-augmented generation, an API, a tool call, a file, or another agent.
Separate Trusted Instructions From External Data
Agents need some way to distinguish what defines their task from what merely provides information for that task.
System instructions, application policy, user intent, retrieved content, and tool output should not collapse into one undifferentiated block of text where every instruction-like sentence competes for influence.
Where the architecture allows it, preserve those boundaries explicitly.
For example:
Trusted System Policy ↓ Authorized User Task ↓ Retrieved External Data — Untrusted ↓ Agent Decision
This does not guarantee that the model will never be influenced by malicious content. It does make the intended trust hierarchy clearer and gives surrounding security controls more information about where content originated.
Detect Suspicious Instructions Without Treating Detection as a Guarantee
Prompt-injection classifiers, content filters, pattern detection, sanitization, and model-based screening can identify suspicious inputs before or while they enter agent context. They are useful controls. They are not an authorization layer.
An attacker may disguise instructions, split them across content, use unusual formatting, exploit another language, or construct input that does not match known detection patterns. False positives also matter because overly aggressive filtering can remove legitimate information the agent needs.
Detection should therefore contribute to a decision rather than carry the entire defense.
Suspicious content might be blocked, isolated, stripped of active influence, sent for additional inspection, or allowed only into a workflow with reduced capabilities.
Minimize the Context Available to the Agent
Every unnecessary piece of retrieved information creates additional exposure.
An agent answering a question about one customer's order should not receive thousands of unrelated customer records simply because the backend can retrieve them. Likewise, a task requiring one document should not automatically load an entire repository into the model's working context. A useful constraint is: Retrieved Context ⊆ Authorized Task-Relevant Context
Context minimization helps in two ways. It reduces sensitive information available for exfiltration and limits the amount of potentially hostile content entering the model.
This is a retrieval and access-control problem as much as a prompt-design problem.
Expose Only the Tools Required for the Task
The same minimization principle applies to tools. A research agent that needs web search and document retrieval probably does not need account deletion, payment modification, administrative configuration, or external messaging capabilities during the same task.
Keep the available tool surface narrow: Available Tools ⊆ Task-Relevant Tools
Tool descriptions and schemas should also be governed and validated. A compromised, malicious, or unexpectedly modified tool can influence agent behavior even when the original user input is harmless.
Reducing tool exposure does not prevent injection, but it gives injected instructions fewer useful capabilities to target.
Validate Tool Calls Before They Reach Protected Systems
A model-generated tool request should be treated as a request, not proof that the operation is legitimate. Validate the tool, operation, resource, parameters, tenant, delegation, and relevant policy before execution.
For consequential actions: Agent Request → Validate Parameters → Evaluate Authority → Apply Policy → Allow / Step-Up / Deny
This is especially important for parameters generated from untrusted context. An injected instruction might not need to select a different tool if it can manipulate the account identifier, destination, query, file path, or transaction value passed to an approved one.
Add Human Approval at High-Consequence Boundaries
Human-in-the-loop controls work best when they are selective. Requiring approval for every agent action creates friction and encourages users to approve requests without meaningful review. Instead, reserve additional approval for operations where the consequence justifies it.
That may include large financial transactions, destructive changes, credential or permission modifications, external transmission of sensitive information, or other actions an organization decides should not occur autonomously.
The agent can still do the preparatory work. The irreversible or high-impact step waits.
Monitor the Full Agent and Tool Chain
Individual tool calls can appear legitimate when viewed in isolation. A document retrieval is normal. A customer lookup is normal. Sending an email may also be normal.
The sequence can tell a different story: External Document Read → Sensitive Record Retrieved → New External Destination Selected → Data Sent
Monitoring agent behavior across the workflow makes these combinations easier to investigate.
Useful audit evidence should preserve the operational chain around the action: Principal → Agent → Context Source → Tool Request → Authorization Decision → Resource → Action → Result
This does not require storing private model reasoning. Security teams need traceable events around what entered the workflow, which capabilities were requested, what policy decided, and what actually executed.
The strongest indirect prompt injection prevention and mitigation strategy is therefore layered. Reduce hostile content entering the decision surface. Minimize the data and tools available to exploit.
Validate requested operations independently. Limit autonomous authority. Monitor what happens afterward. And assume those controls may need to reevaluate trust as the workflow changes. That is where Zero Trust becomes particularly useful for agentic systems.
Indirect Prompt Injection in a Zero Trust Architecture Requires Continuous Verification
Indirect prompt injection exposes a weakness in any architecture that treats an earlier trust decision as permanent.
A user may have authenticated correctly. The agent may have legitimate access to an application. The retrieved document may come from an approved repository. None of those facts means the next tool request should automatically be trusted.
Zero Trust changes the assumption. Instead of asking whether the agent was trusted when the workflow began, the system keeps evaluating whether the current identity, delegated authority, resource, context, and requested action still satisfy policy.
For an agentic workflow, that can look like: Verify Identity → Validate Delegation → Check Tenant → Validate Resource → Evaluate Tool → Evaluate Action → Allow / Step-Up / Deny
The agent does not earn permanent trust simply by passing the first checkpoint.
Never Trust Content Simply Because Its Source Was Authorized
Indirect prompt injection makes source-based trust particularly fragile.
An employee may have permission to read a shared document. An agent may have permission to access that employee's mailbox. A support system may correctly allow the agent to retrieve a customer ticket. Those are access decisions. They are not guarantees about the safety of the content.
A Zero Trust approach keeps the two questions separate: Is the agent authorized to retrieve this content?
and: Should instructions found inside this content influence a protected action?
A legitimate resource can contain attacker-controlled information. Trust should therefore be evaluated at the point where that information begins affecting another security boundary.
Reevaluate Authority When the Agent Attempts an Action
An agent may start a task with valid permissions and later request an operation that was never part of the original purpose.
Consider: User Requests Invoice Summary → Agent Reads Document → Injection Alters Plan → Agent Requests Payment Change
The first two operations may be fully authorized. That should not create inherited approval for the third. Runtime authorization allows the system to evaluate the payment request using the conditions that exist when the action is attempted:
Who is the principal?
Which agent is acting?
What authority was delegated?
Which tenant owns the resource?
What operation is being requested?
Does the current task justify it?
If those conditions do not align, an earlier successful authentication should not override them.
Use Short-Lived and Resource-Scoped Authority
Long-lived credentials make changing trust difficult to enforce.
An agent may complete one task, begin another, encounter malicious context, or remain active after the user's permissions have changed. A credential that remains broadly valid throughout those transitions gives the agent authority that may no longer match its current purpose.
A tighter model is: Current Task → Required Resource → Required Scope → Limited Lifetime
An agent authorized to read CRM records should not assume the same credential grants access to payment systems. An agent authorized for one short-lived workflow should not retain that authority indefinitely because the process once required it.
Resource-scoped, time-bounded access reduces what an injected instruction can reuse or redirect.
Revalidate Long-Running and Asynchronous Agent Tasks
Agentic workflows do not always execute immediately. An agent might wait for another system, resume after an approval, process a scheduled task, or continue a workflow hours after the user initiated it. Conditions can change during that gap.
For example: User Delegates Task → Agent Pauses → User Permission Is Removed → Agent Resumes
If the agent relies only on the authorization decision made at the beginning, it may continue using authority the principal no longer holds.
The same issue appears when a delegation expires, a tenant relationship changes, a tool is disabled, or the risk associated with an operation increases.
Resumption should trigger reevaluation where those changes matter. Previously Valid Authority ≠ Current Authority
Increase Verification When the Consequence Changes
Zero Trust does not mean every action needs the same amount of verification. An agent retrieving a public product document and an agent changing an administrator's authentication settings present different risks. The controls should reflect that difference.
A workflow may progress normally until the requested operation crosses a defined threshold:
Read → Allow
Analyze → Allow
Prepare Change → Allow
Commit Sensitive Change → Step-Up
Operation Outside Delegation → Deny
Step-up authentication, explicit approval, or another policy check can be introduced when the consequence warrants it rather than forcing the same friction into every agent interaction.
Revoke Authority When Trust Conditions Change
Continuous verification also needs an exit path. If an agent begins behaving unexpectedly, a credential is exposed, a delegation expires, or a tool becomes unsafe, teams need to stop the relevant authority without waiting for every existing token or workflow to disappear naturally.
Depending on the architecture, that can mean revoking credentials, ending delegated access, terminating an agent task, disabling a tool, or blocking access to a protected resource.
This is another reason to separate agent identity from principal identity. Security teams can contain the agent workflow without necessarily disabling the user who originally initiated it.
Zero Trust cannot prevent every malicious instruction from reaching an AI model. What it can do is prevent one successful trust decision from silently carrying through the rest of the workflow.
For indirect prompt injection, that matters. The content may change. The agent's plan may change. The requested tool may change. The resource may change. The consequence may change. Authorization should be able to change with them.
Indirect Prompt Injection Defense Checklist for Engineering and Security Teams
Indirect prompt injection testing should cover the complete path between untrusted content and a protected action. Testing only whether the model recognizes a malicious instruction misses the larger question: what can happen if the model does not recognize it?
Start with the full execution path: External Content → Agent Context → Agent Decision → Tool Request → Authorization → Protected Resource → Action
Then test the controls at each boundary.
| Security Check | What Engineering Teams Should Verify |
|---|---|
| External content | Emails, webpages, documents, API responses, tool outputs, and user-generated content are treated as potentially untrusted |
| Context boundaries | System instructions, user intent, retrieved data, and tool output remain distinguishable where the architecture supports it |
| Context retrieval | The agent retrieves only data authorized and relevant to the current task |
| Content screening | Prompt injection detection and filtering supplement other controls rather than acting as the sole defense |
| Agent identity | Each agent can be identified independently from the principal and other agents |
| Principal context | The system can determine on whose behalf the agent is acting |
| Delegated authority | Agent permissions remain within the authority delegated for the current task |
| Credentials | Agent access is short-lived, scoped, resource-appropriate, and revocable |
| Tenant isolation | Tenant or organization context survives retrieval, tool invocation, and downstream authorization |
| Tool exposure | Only tools required for the current workflow are available to the agent |
| Tool integrity | Tool definitions, schemas, and material changes are governed and validated |
| Tool parameters | Model-generated resource IDs, destinations, values, queries, and other sensitive parameters are validated |
| Runtime authorization | Consequential operations are authorized when execution is requested, not only when the session begins |
| Autonomous authority | The agent cannot autonomously perform actions beyond defined consequence thresholds |
| Human approval | High-impact operations require additional approval where policy demands it |
| Multi-agent delegation | A downstream agent cannot receive greater authority than the delegating agent is permitted to pass |
| Auditability | Security teams can trace principal, agent, context source, tool request, authorization decision, action, and result |
| Revocation | Agent credentials, delegation, tools, or active authority can be terminated when risk conditions change |
The exact controls will differ by application. A research assistant reading public webpages does not need the same authorization architecture as an agent capable of modifying production infrastructure. The checklist should reflect the worst action the agent can actually execute, not simply the sensitivity of its original prompt.
Test Failure Paths, Not Just Successful Agent Tasks
A normal functional test might confirm that an agent can read a document, call the correct tool, and complete a task. Security testing should deliberately make that workflow go wrong.
Feed the agent content containing instructions that conflict with the user's task. Place adversarial text in documents, emails, webpages, retrieved records, and tool output. Change resource identifiers. Attempt to cross tenant boundaries. Ask the manipulated agent to use tools unrelated to the delegated task.
Then verify that the surrounding controls stop the consequence.
For example:
Malicious Document → Agent Requests Unauthorized Data Export → Deny
Injected Email → Agent Requests High-Value Transaction → Step-Up or Deny
Tenant A Context → Agent Requests Tenant B Record → Deny
Injected Tool Output → Agent Attempts Unapproved External Message → Deny
Agent A Manipulated → Excessive Authority Delegated to Agent B → Deny
Expired Delegation → Agent Resumes Task → Reauthorize or Deny
These tests reveal something prompt-injection benchmarks alone cannot: whether a successful manipulation can cross the execution boundary.
Test the Complete Containment Chain
A mature test should be able to follow one adversarial input from ingestion to its final outcome:
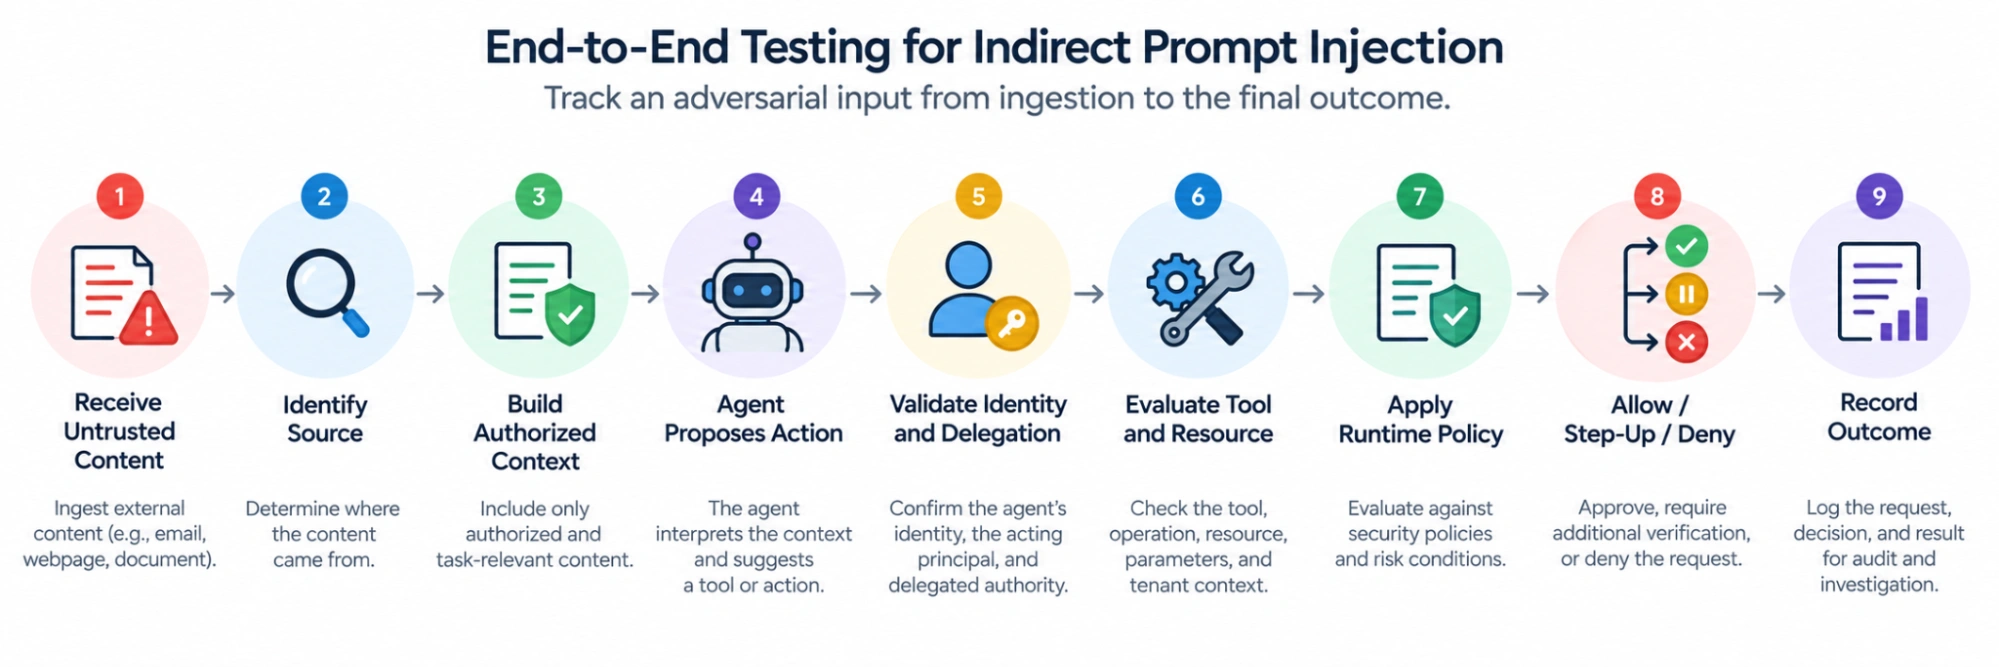
For high-risk agent systems, engineering teams should be able to answer a few practical questions.
Can the agent reach data unrelated to the current task?
Can malicious context change which tenant or resource it accesses?
Can one tool's output trigger an unrelated privileged tool?
Can an agent reuse authority after delegation expires?
Can a downstream agent gain permissions the upstream agent did not possess?
If the model is successfully manipulated, what is the most consequential action that can execute before another control intervenes?
That last question is particularly useful.
Indirect prompt injection defenses should not be evaluated only by how often they prevent the model from following malicious instructions. They should also be evaluated by how effectively the architecture contains the agent when prevention fails.
Containing Indirect Prompt Injection With LoginRadius Agentic IAM
Indirect prompt injection defenses usually begin with the content itself: identify suspicious instructions, isolate untrusted data, reduce unnecessary context, and prevent external content from overriding trusted instructions.
Those controls matter. But once an agent can access APIs, tools, MCP servers, customer data, or other protected resources, another question becomes just as important: what happens if malicious content still influences the agent?
LoginRadius Agentic IAM addresses this part of the problem at the identity and access layer. Instead of assuming a correctly authenticated agent will always make the correct decision, organizations can establish distinct agent identities, constrain delegated access, enforce scoped authorization, and preserve accountability around the actions agents perform.
The security path becomes: Principal → Agent Identity → Delegated Authority → Policy → Tool or API → Action → Audit
Prompt injection may influence the proposed action. It should not silently rewrite the authority behind it.
Establish Verifiable Identities for AI Agents
Agents should not disappear behind a user's identity or a shared service account.
LoginRadius supports managing AI agents as distinct identities independent of users and applications. Each agent can have its own lifecycle and access, giving downstream systems a defined actor to authenticate and govern.
This separation is particularly useful during an indirect prompt injection incident. Security teams can identify which agent made the request and manage that agent's access without automatically treating the principal as the executing actor.
Instead of: User Credential → Agent → Protected System
the relationship remains visible: User → Identified Agent → Protected System
That distinction improves both containment and accountability.
Preserve Delegated Authority Instead of Giving Agents Full User Access
Agents frequently need to act for someone else. That does not mean they need everything that person can access.
LoginRadius supports delegated authorization patterns that preserve the relationship between the user and the agent while limiting the permissions available to the agent.
The authority boundary should remain: Agent Authority ≤ Delegated Authority ≤ Principal Authority
If an employee asks an agent to retrieve a particular report, an injected instruction should not be able to turn that delegation into unrestricted access to every resource available to the employee.
Keeping delegation scoped also makes the original task relevant to downstream authorization rather than relying solely on the fact that the principal once approved the agent.
Enforce Fine-Grained, Scoped Authorization
Authentication establishes which agent is making a request. Fine-grained authorization determines what that agent is permitted to do. LoginRadius supports scoped authorization and per-agent, per-action permissions, allowing access to be narrowed around the operations required by an agent workflow.
That is important when prompt injection changes the requested action.
An agent may be permitted to read a customer record without being permitted to delete it. It may retrieve transaction information without having autonomous authority to change a payment destination. The model can request the operation.
The authorization layer still decides whether that operation belongs within the agent's permitted scope.
Limit Credential Exposure With Short-Lived Access
Broad, persistent credentials make indirect prompt injection more consequential because manipulated agents can potentially reuse the same authority across tasks and systems.
LoginRadius supports short-lived, scoped tokens for AI agent access, along with centralized credential lifecycle management and revocation.
The intended relationship is narrow: Agent → Required Scope → Intended Resource → Limited Lifetime
If the workflow changes or the agent no longer requires the access, that authority does not need to remain indefinitely available.
This reduces the amount of reusable privilege sitting behind the model when hostile context influences its decisions.
Maintain Auditability, Governance, and Revocation
Containment also depends on knowing what happened after an agent encountered suspicious content.
LoginRadius provides visibility into agent activity, token usage, delegation, and authorization decisions so teams can trace activity back through the identity chain. Agent credentials and access can also be revoked or rotated independently when required.
For an agentic workflow, the useful audit path is: Principal → Agent → Delegated Authority → Requested Action → Authorization Decision → Protected Resource → Result
That makes it possible to investigate more than whether the model produced an unusual response. Teams can determine which agent acted, whose authority it carried, what access it requested, and what ultimately executed.
LoginRadius does not replace prompt-injection detection, context isolation, secure tool design, or model-level defenses. It addresses another critical layer: limiting the authority available after an agent has been influenced.
That gives indirect prompt injection a smaller path from manipulated reasoning to real-world impact.
The agent may be tricked into requesting an action. Identity and authorization controls determine whether it gets to perform it.
Conclusion
Indirect prompt injection is difficult because the malicious instruction can arrive through the same emails, documents, webpages, APIs, and tool outputs an AI agent legitimately needs to perform its work. Blocking every untrusted input is neither realistic nor sufficient.
A stronger security model assumes that some hostile content may reach the agent. What happens next should not depend entirely on whether the model recognizes the attack.
Untrusted Content → Agent Decision → Identity → Delegated Authority → Runtime Policy → Action
Keep external content separated from trusted instructions. Minimize the context and tools available to the agent. Give agents distinct identities and scoped authority. Evaluate consequential actions outside the model, and require additional approval when autonomous authority should end.
The goal is containment. An attacker may manipulate what an agent decides to request. That should not automatically give them the authority to access sensitive data, cross tenant boundaries, invoke privileged tools, or execute high-impact operations.
With LoginRadius Agentic IAM, organizations can establish verifiable agent identities, delegated access, fine-grained authorization, short-lived credentials, and auditable agent activity around AI workflows.
Explore LoginRadius Agentic IAM to keep agent identity, authority, and execution under control even when untrusted content enters the workflow.
FAQs
Q: What is indirect prompt injection?
A: Indirect prompt injection is an attack where malicious instructions are embedded in external content that an AI system later processes. Common sources include webpages, emails, documents, database records, API responses, and tool outputs.
Q: What is the difference between direct and indirect prompt injection?
A: Direct prompt injection sends malicious instructions directly through a user prompt or input. Indirect prompt injection places them in external content that the AI later retrieves or encounters while completing a task.
Q: How does indirect prompt injection work in AI agents?
A: An agent retrieves attacker-controlled content, which enters its context and may influence its reasoning or tool selection. If surrounding controls are weak, the manipulated decision can lead to unintended data access or downstream actions.
Q: What are examples of indirect prompt injection attacks?
A: Examples include malicious instructions hidden in emails, webpages, PDFs, support tickets, retrieved documents, or tool outputs. These instructions may attempt to trigger data disclosure, unauthorized tool use, privilege abuse, or other unintended actions.
Q: Why is indirect prompt injection dangerous for agentic AI?
A: AI agents can connect model decisions to tools, APIs, sensitive data, and business systems. This means successful prompt injection may affect more than generated text—it can potentially influence actions against external resources.
Q: How can organizations prevent indirect prompt injection?
A: Use layered defenses such as context isolation, prompt-injection detection, minimal data and tool exposure, scoped credentials, runtime authorization, parameter validation, monitoring, and human approval for high-impact actions.
Q: Can authentication stop indirect prompt injection attacks?
A: Authentication identifies the user or agent but does not determine whether retrieved content contains malicious instructions. Identity and authorization controls instead help contain the impact by limiting what a manipulated agent can access or execute.
Q: How does Zero Trust reduce indirect prompt injection risk?
A: Zero Trust continuously evaluates identity, delegated authority, resources, tools, and requested actions instead of trusting an agent after initial authentication. This helps prevent manipulated reasoning from automatically becoming authorized execution.